
NEWS
Nvidia’s DSX POD Turns AI Factories Into Grid Loads
Nvidia’s DSX POD ships Vera Rubin racks in 14 days and adds grid-flex software so AI factories can connect where water and power boards push back.

Nvidia said on October 21, 2026 that a factory-built DSX POD can put a Vera Rubin AI factory on a prepared site in as little as 14 days. Jensen Huang used the GTC Berlin keynote to wrap that box in a larger pitch: cooling that uses almost no water at the fence, and software that lets the same halls shed power when the grid asks.
The water slides are easy to repeat. The second move is the one that changes who says yes to a gigawatt hall. DSX Flex and DSX MaxLPS treat an AI factory as a controllable load, which is how operators argue for a grid hookup in markets that have already run out of cheap power and cheap water.
Seven Racks, 17 Kilometers of Cable, One Container
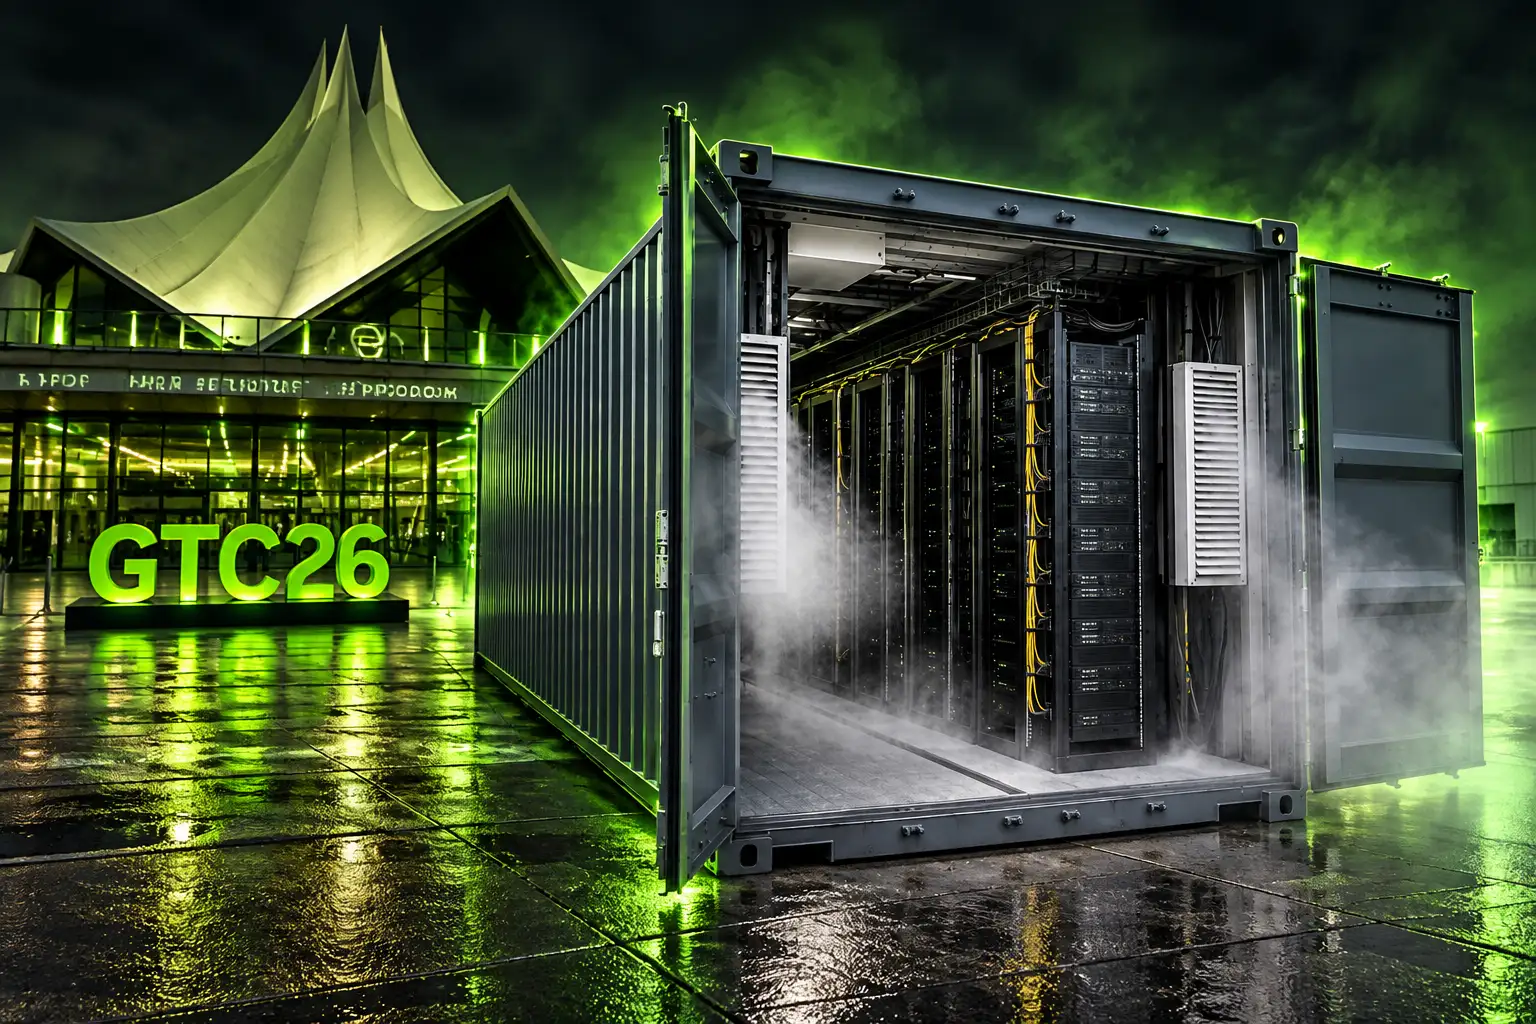
DSX POD is a partner-built reference design for a complete Vera Rubin AI factory, assembled inside modular containers, cabled, piped and tested before it leaves the plant. Huang’s keynote line was blunt: it starts with Vera Rubin NVL72, and seven liquid-cooled compute racks tied together with 17 kilometers (11 miles) of Spectrum-X cable form one Vera Rubin DSX POD.
Partners finish rack-to-rack cabling, wiring, piping and functional checks at the factory, then ship the unit to a site that already has power, cooling and network feeds waiting. Nvidia says that shift is how on-site work falls from six months to as little as 14 days, reducing deployment time from six months once those utilities are ready.
THE BOX NVIDIA IS SELLING
- Compute block: Seven liquid-cooled Vera Rubin NVL72 racks arrive as one factory-tested unit.
- Scale-out fabric: 17 kilometers (11 miles) of Spectrum-X cable are pulled and checked before shipment.
- On-site clock: Nvidia’s target is as little as 14 days after a prepared site is ready, down from six months of field assembly.
- First shipments: Partners are aiming to deliver units worldwide in early 2027.
Huang put the money case in one number. He said a three-month delay can mean $10 billion in lost revenue, because an AI factory starts earning when it produces tokens. The Berlin line was the same idea in fewer words.
An AI factory creates value when it starts producing tokens
Jensen Huang, founder and CEO, Nvidia, GTC Berlin keynote
He called the move a change in how data halls get built, not a new chip launch. Cabling, liquid cooling and rack-level power leave the construction site and go back into the supply chain. Nvidia also tied the design to 800 VDC power delivery, which cuts conversion stages between the yard and the rack.
AI builders need computing capacity they can put to work sooner.
We introduced DSX POD at NVIDIA GTC Berlin: AI factories integrated and tested before delivery, enabling deployment at prepared sites in as little as 14 days. pic.twitter.com/0Ax7yHMvBp
— NVIDIA (@nvidia) October 21, 2026
Nvidia Puts Dry Coolers Where Towers Used to Sit
The companion Berlin briefing was about water. Standard cooling towers dump heat by evaporating water and then replacing it. DSX reference designs run liquid through the computers in a closed loop, then reject that heat through outdoor dry coolers, large radiators that push warmth into air without boiling water away.
Vera Rubin gear is built for 100% liquid cooling, with coolant allowed to run as warm as 45 degrees Celsius. That high set point is the whole trick. Warm liquid can give up heat to outdoor air in many climates without a tower and without a chiller running all year. Nvidia says that cut in facility cooling water can reach 100%, and that a 2-gigawatt campus on this design can save 54 million liters of water a day against tower-based plants, about the daily use of 180,000 households.
COOLING AT THE FENCE, NVIDIA’S FIGURES
| Design | How heat leaves the site | Facility cooling water | Hot-weather backup |
|---|---|---|---|
| Tower plant | Evaporation in cooling towers | Continual makeup water | Towers keep running |
| DSX dry-cooler loop | Closed liquid loop into outdoor dry coolers | Near zero; up to a 100% cut vs towers | Extra mechanical cooling in the hottest local weather |
| 2 GW DSX campus | Same dry-cooler method at campus scale | 54 million liters a day saved vs towers | Local climate decides if chillers kick in |
Those liters stop at the property line. Nvidia is counting water used to cool the computers, not water used to make the electricity that feeds them, and not water used to make the chips. Local weather still matters. The company says some climates will need extra mechanical cooling in extreme heat, so the 100% figure is a design ceiling, not a promise for Phoenix in July.
Huang still branded the platform “responsible by design.” In Berlin that phrase sat next to the household comparison, which is the version of the pitch a water board can hear.
The Factory Will Shed Power When Asked
Water gets the headline. Power gets the interconnection. Ian Buck, speaking to reporters before the Berlin keynote, said that when there is an energy spike and “the grid needs an extra gigawatt, our data centers can be a resource to respond to that need.”
the grid needs an extra gigawatt, our data centers can be a resource to respond to that need
Ian Buck, Nvidia, media briefing ahead of GTC Berlin
DSX Flex is the software that makes that sentence operational. It lets operators change workload power against utility needs, demand-response events and energy prices, and it can mix grid power with on-site renewables and storage. Nvidia’s own product language is that this helps AI factories operate as flexible loads and “enable faster grid connection.” In March, the company had already claimed that flexible factories could unlock up to 100 GW of capacity on the existing U.S. power system. Berlin brought the same idea to Europe with a live trial attached.
In that early trial, Emerald AI, EPRI, Nebius, the U.K. National Grid and Nvidia cut cluster power draw by up to 40 percent on a Blackwell Ultra GPU cluster during simulated grid events, while critical jobs kept running. EPRI’s write-up of the UK’s first live DCFlex demonstration adds the timing: the shed happened within seconds, and the cluster hit 100% compliance with more than 200 requested power targets.
That is the permit logic. A utility that can reclaim a slice of a gigawatt on short notice can approve a hookup it would otherwise refuse. Flex does not make a 2 GW campus small. It makes the campus interruptible, which is the trait grids pay for and planners will trade for a faster yes.
Warren Barkley, vice president of DSX product management at Nvidia, framed Europe in those terms. “Europe’s technology leadership depends on how efficiently we turn power and infrastructure into intelligence,” he said. Hitachi Energy is already building a link between its energy management system and DSX Flex, so grid, generation and storage can track workload demand instead of treating the hall as a brick.
What MaxLPS Does Inside a Fixed Power Budget
Flex talks to the utility. MaxLPS talks to the rack. Nvidia says DSX MaxLPS dynamically allocates power inside a factory’s provisioned budget so operators can generate the same number of tokens with up to 30 percent less power. The same software can be spent the other way: the MaxLPS product page says it can enable up to 40 percent more compute inside the same power budget, which is a different use of the spare watts, not a second measurement of the 30 percent claim.
Two partner tests are the evidence Nvidia is willing to put on paper, and they are not Vera Rubin PODs. They are earlier racks running MaxLPS code.
MAXLPS RESULTS NVIDIA PUBLISHED
| Operator | Hardware | Power box | Result |
|---|---|---|---|
| Lambda | HGX B200 systems | Fixed cluster budget | 24% more cluster token throughput; 19% more GPU capacity |
| Nscale | Four GB300 NVL72 racks, Iceland | 264 kW provisioned | 49% higher inference throughput; 37% more managed GPU capacity |
CoreWeave, Firmus, Google Cloud, IREN, Lambda, Nebius, Nscale and Sharon AI are exploring MaxLPS. Nscale is also testing Flex and using DSX Sim to model power and cooling for sites in Portugal and Iceland before steel goes in.
Europe’s AI ambitions demand that we make every megawatt count. With NVIDIA DSX, we’re building AI factories that deliver more compute from available power, respond to grid conditions and move faster from design to deployment.
Josh Payne, founder and CEO, Nscale
The measured gains sit on Blackwell-class iron. Vera Rubin NVL72 is the rack the POD is built around, and Nvidia says Rubin testing is still in progress. MaxLPS is the operating method Nvidia wants sitting on top of those racks when the containers start to arrive.
The 14-Day Clock Starts After the Site Is Ready
The 14-day figure is doing a lot of work in a short sentence. Nvidia’s own wording always attaches it to a prepared site. Power, cooling, networking and the rest of the yard still have to be there. The factory can pull cable and pressure-test pipes. It cannot pour a substation or win a water permit.
That is the practical limit people who commission halls keep repeating, and it is correct. A container that is ready in 14 days still waits on the feeders in the ground. Factory validation shortens the box. The site still sets when the first production token leaves the building.
WHAT WE KNOW
- The product: DSX POD is a reference design, not a priced SKU Nvidia will drop-ship itself.
- The clock: As little as 14 days applies after site power, cooling and network are ready, against six months of on-site assembly.
- The date: Partners are targeting worldwide delivery in early 2027.
- The grid trial: A Blackwell Ultra cluster in the U.K. shed up to 40 percent of power draw while critical jobs kept running.
WHAT IS UNCONFIRMED
- A 14-day go-live: No customer has published a completed 14-day POD turn-up.
- Vera Rubin MaxLPS numbers: The published throughput gains are on B200 and GB300 systems.
- Price: Nvidia has not posted a POD price or a per-rack list price.
- Hot-climate water: The 100% facility-water cut still needs extra mechanical cooling in extreme heat, and Nvidia has not published hours-per-year by city.
Huang also described a looser range in the keynote, from about four to five months down to about a month, once wiring and test move into the supply chain. The press figure remains as little as 14 days. Both clocks assume the boring work outside the container is already done.
Dell, Vertiv and the Early 2027 Partner Run
Nvidia is not welding the boxes. A named list of computer makers, cooling firms, power vendors and a few less obvious names is supposed to manufacture and deliver DSX POD plants. The Berlin roster is Anduril, Armada, Bull, Crusoe, DayOne, Dell Technologies, Delta, Eaton, Foxconn (Ingrasys), GIGABYTE, HPE, Lenovo, Pegatron, Quanta Cloud Technology, Schneider Electric, Vertiv and Wistron.
WHO IS ON THE BUILD LIST
- Systems houses: Bull, Dell Technologies, GIGABYTE, HPE, Lenovo, Foxconn (Ingrasys), Pegatron, Quanta Cloud Technology and Wistron take the compute side.
- Power and cooling: Delta, Eaton, Schneider Electric and Vertiv bring yard gear, including qualified coolant plants under Nvidia’s DSX program.
- Site and energy names: Crusoe, DayOne, Armada and Anduril sit on the same list as the server makers, which is how a defense firm and an energy-backed operator end up in a cooling brief.
Around that POD list, Nvidia is lining up a wider European stack. Trane Technologies published seven thermal reference designs, including three 250-megawatt DSX cooling designs. Vertiv’s 2.3-megawatt CoolChip coolant unit and Trane’s LiquidStack GigaModular have qualified under DSX categories. GE Vernova, Hitachi Energy and Siemens Energy are on power and digital-twin work. ABB is pushing 800 VDC kit through its Infinitus Direct Current line and building SimReady models for Nvidia’s design tools.
DSX OS, still in developer preview, is the software layer meant to configure networks, manage racks and prove a cluster before production jobs arrive. Cloud operators including Aleria, Cassava, CoreWeave, Crusoe, Firmus, Firebird, G42, GMI Cloud, IREN, Lambda, Nebius, Nscale, Radiant, Sharon AI and Volta are looking at those pieces. That is not a live POD census. It is the industrial bench Nvidia wants in place before early 2027.
Partners are aiming to deliver the first DSX POD units in early 2027. The Berlin pitch is that those boxes will land on sites that already have power, pipes and a utility willing to connect them because it can take the power back.

Final Fantasy Resonance Turns a Dead Gacha Into HD-2D

PHP2Shell Forced Sites Offline While Exploits Stalled

Kindle+ Folds AI Audiobooks Into the Page-Read Fund

Chip Stocks Fall as the Bond Rally Cheapens AI Spend

Comcast’s Record Odyssey Quarter Doubles as the Exit

Microsoft 365 Auth Fault Took Down Exchange and Teams

Xbox Caps Game Pass Cloud Gaming at 15 Hours

OpenClaw 2.0 Ships a Team Workplace With Host-Trust Defaults

OpenAI Unveils GPT-6 Astra With a Critical Cyber Label

Diesel Breaks Its Record as the White House Claims Credit
-
 NEWS2 months ago
Microsoft 365 Auth Fault Took Down Exchange and Teams
-
 GAMING2 months ago
Xbox Caps Game Pass Cloud Gaming at 15 Hours
-
 NEWS2 months ago
OpenAI Unveils GPT-6 Astra With a Critical Cyber Label
-
 NEWS2 months ago
OpenClaw 2.0 Ships a Team Workplace With Host-Trust Defaults
-
 BUSINESS2 months ago
Diesel Breaks Its Record as the White House Claims Credit
-

 LIFESTYLE2 months ago
Squishy Dumpling Toys Recalled After Hiding Illegal Water Beads
-

 BUSINESS2 months ago
ChargePoint Stock Rally Prices Wilmer’s Three-Year Cash Plan
-

 AUTO2 months ago
Tesla Puts Its Wheel-Free Cybercab on Austin Streets